

 Free Demo


Three versions of Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam bootcamp for better study
There are three versions of Associate-Developer-Apache-Spark-3.5 test questions: Databricks Certified Associate Developer for Apache Spark 3.5 - Python for now with high accuracy and high quality. All these versions of Associate-Developer-Apache-Spark-3.5 training online questions include the key point information that you need to know to pass the test. We will give you some more details of three versions, and all of them were designed for your Databricks Associate-Developer-Apache-Spark-3.5 exam: PDF version-Legible to read and remember, support customers' printing request. Software version- It support simulation test system, and several times of setup with no restriction. Remember support Windows system users only. Databricks Associate-Developer-Apache-Spark-3.5 App online version- Be suitable to all kinds of equipment or digital devices. Be supportive to offline exercise on the condition that you practice it without mobile data. So our three versions of Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam simulation questions can make different buyers satisfying.
Perfect Databricks Certified Associate Developer for Apache Spark 3.5 - Python practice exam questions made by Professional group
We have always been attempting to help users getting undesirable results all the time. That is the reason why we invited a group of professional experts who dedicate to the most effective and accurate Associate-Developer-Apache-Spark-3.5 test questions: Databricks Certified Associate Developer for Apache Spark 3.5 - Python for you. To sort out the most useful and brand-new contents, they have been keeping close eye on trend of the time in related area, so you will never be disappointed about our Associate-Developer-Apache-Spark-3.5 training online questions once you make your order. And you can absolutely get the desirable outcomes. They not only compile the most effective Associate-Developer-Apache-Spark-3.5 original questions for you, but update the contents with the development of society in related area, and we will send the new content about the Databricks Associate-Developer-Apache-Spark-3.5 exam to you for one year freely after purchase.
Nowadays, a mass of materials about the Databricks exam flooded into the market and made the exam candidates get confused to make their choice, and you may be one of them. With the high quality and high passing rate of our Associate-Developer-Apache-Spark-3.5 test questions: Databricks Certified Associate Developer for Apache Spark 3.5 - Python, we promised that our Associate-Developer-Apache-Spark-3.5 training online questions are the best for your reference. So it is a well advised action to choose our materials. Now please take a thorough look about the features of the Associate-Developer-Apache-Spark-3.5 original questions as follow and you will trust our products, so does our services.
Aftersales service 24/7
We have a group of ardent employees who are aiming to offer considerable amount of services for customers 24/7. We are not only assured about the quality of our Associate-Developer-Apache-Spark-3.5 test questions: Databricks Certified Associate Developer for Apache Spark 3.5 - Python, but confident about the services as well. So we have been trying with a will to strengthen our ability to help you as soon as possible. Our Associate-Developer-Apache-Spark-3.5 original questions speak louder than words, if you have any other questions about our Associate-Developer-Apache-Spark-3.5 training online materials, contact with us and we will solve them for you with respect and great manner. At latest, you can absolutely pass exam with you indomitable determination and our Associate-Developer-Apache-Spark-3.5 test questions: Databricks Certified Associate Developer for Apache Spark 3.5 - Python.
After purchase, Instant Download Associate-Developer-Apache-Spark-3.5 Dumps: Upon successful payment, Our systems will automatically send the product you have purchased to your mailbox by email. (If not received within 12 hours, please contact us. Note: don't forget to check your spam.)
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Troubleshooting and Tuning | 10% | - Performance Optimization
|
| Topic 2: Structured Streaming | 10% | - Streaming Applications
|
| Topic 3: Using Spark SQL | 20% | - Spark SQL Operations
|
| Topic 4: Using Pandas API on Spark | 5% | - Pandas API
|
| Topic 5: Developing Apache Spark DataFrame API Applications | 30% | - DataFrame Operations
|
| Topic 6: Apache Spark Architecture and Components | 20% | - Spark Architecture
|
| Topic 7: Using Spark Connect to Deploy Applications | 5% | - Spark Connect
|
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
A data engineer writes the following code to join two DataFrames df1 and df2:
df1 = spark.read.csv("sales_data.csv") # ~10 GB
df2 = spark.read.csv("product_data.csv") # ~8 MB
result = df1.join(df2, df1.product_id == df2.product_id)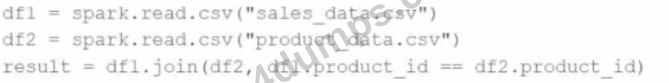
Which join strategy will Spark use?
- A. Shuffle join, as the size difference between df1 and df2 is too large for a broadcast join to work efficiently
- B. Shuffle join, because AQE is not enabled, and Spark uses a static query plan
- C. Shuffle join because no broadcast hints were provided
- D. Broadcast join, as df2 is smaller than the default broadcast threshold
Correct Answer: D 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
Which configuration can be enabled to optimize the conversion between Pandas and PySpark DataFrames using Apache Arrow?
- A. spark.conf.set("spark.pandas.arrow.enabled", "true")
- B. spark.conf.set("spark.sql.execution.arrow.enabled", "true")
- C. spark.conf.set("spark.sql.execution.arrow.pyspark.enabled", "true")
- D. spark.conf.set("spark.sql.arrow.pandas.enabled", "true")
Correct Answer: C 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
A Spark application is experiencing performance issues in client mode because the driver is resource-constrained.
How should this issue be resolved?
- A. Switch the deployment mode to local mode
- B. Add more executor instances to the cluster
- C. Switch the deployment mode to cluster mode
- D. Increase the driver memory on the client machine
Correct Answer: C 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
Given a DataFrame df that has 10 partitions, after running the code:
result = df.coalesce(20)
How many partitions will the result DataFrame have?
- A. 1
- B. Same number as the cluster executors
- C. 20
- D. 10
Correct Answer: D 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
17 of 55.
A data engineer has noticed that upgrading the Spark version in their applications from Spark 3.0 to Spark 3.5 has improved the runtime of some scheduled Spark applications.
Looking further, the data engineer realizes that Adaptive Query Execution (AQE) is now enabled.
Which operation should AQE be implementing to automatically improve the Spark application performance?
- A. Collecting persistent table statistics and storing them in the metastore for future use
- B. Optimizing the layout of Delta files on disk
- C. Dynamically switching join strategies
- D. Improving the performance of single-stage Spark jobs
Correct Answer: C 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).


